interp-engine
interp-engine is the library that Neuronpedia uses to run models. It does all of Neuronpedia's work that needs a model: activations, steering, the Jacobian Lens, NLAs, and circuit tracing. It is open source, and you can use it for your own research.
Start here: interp-engine.org | Docs | GitHub | Blog post
Why Use It
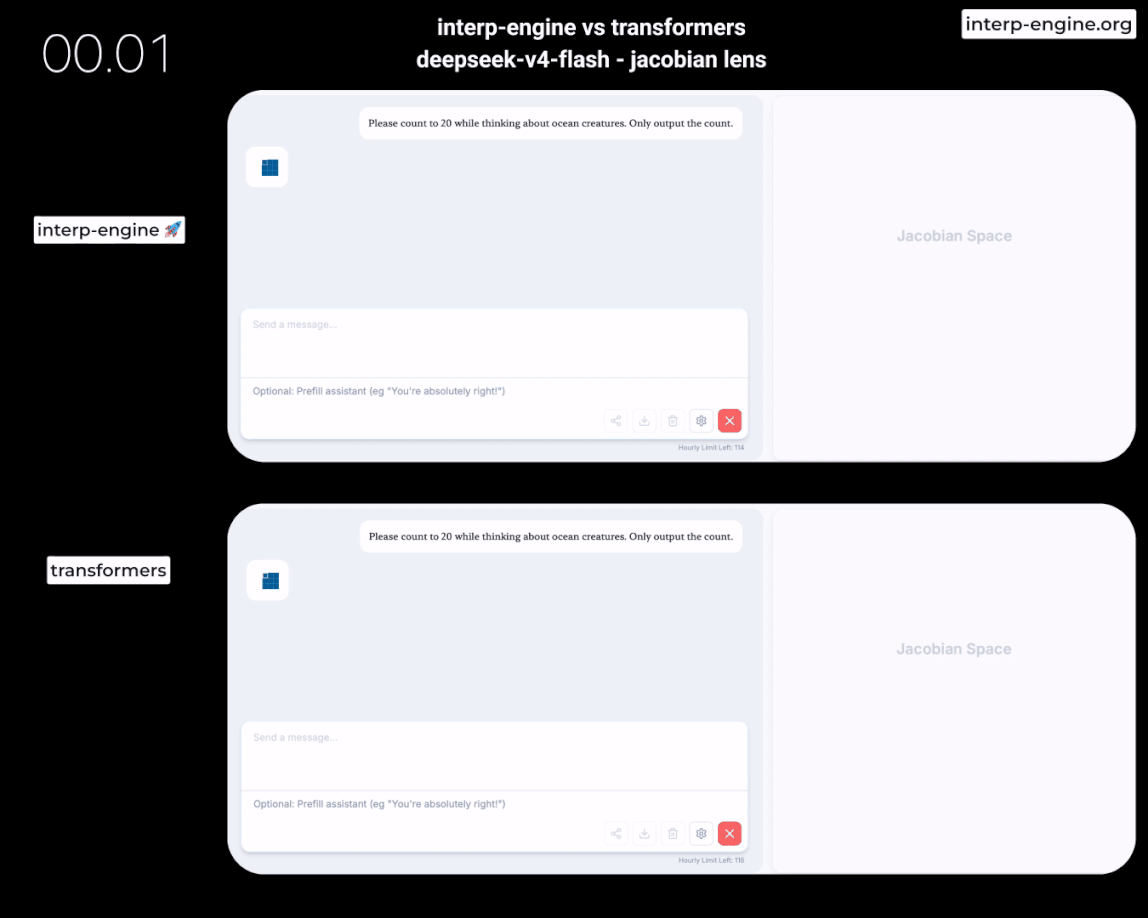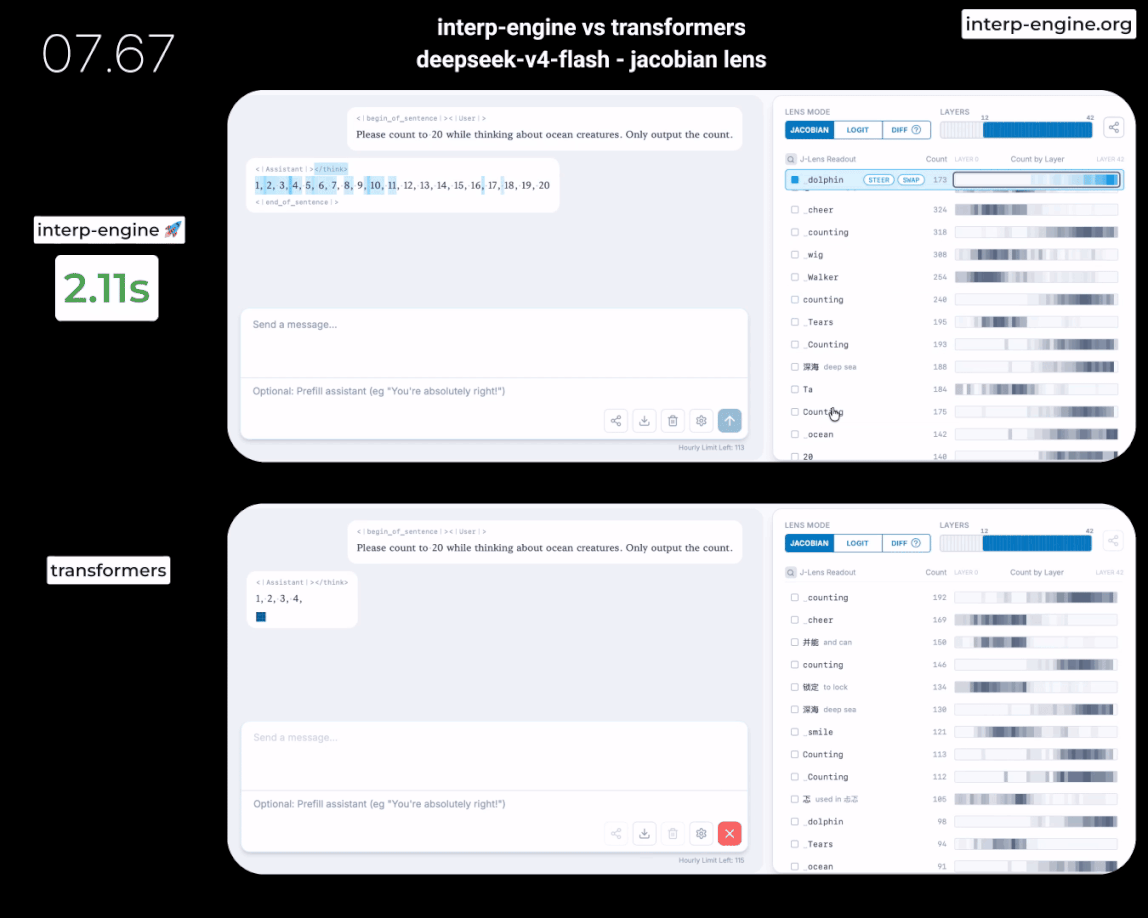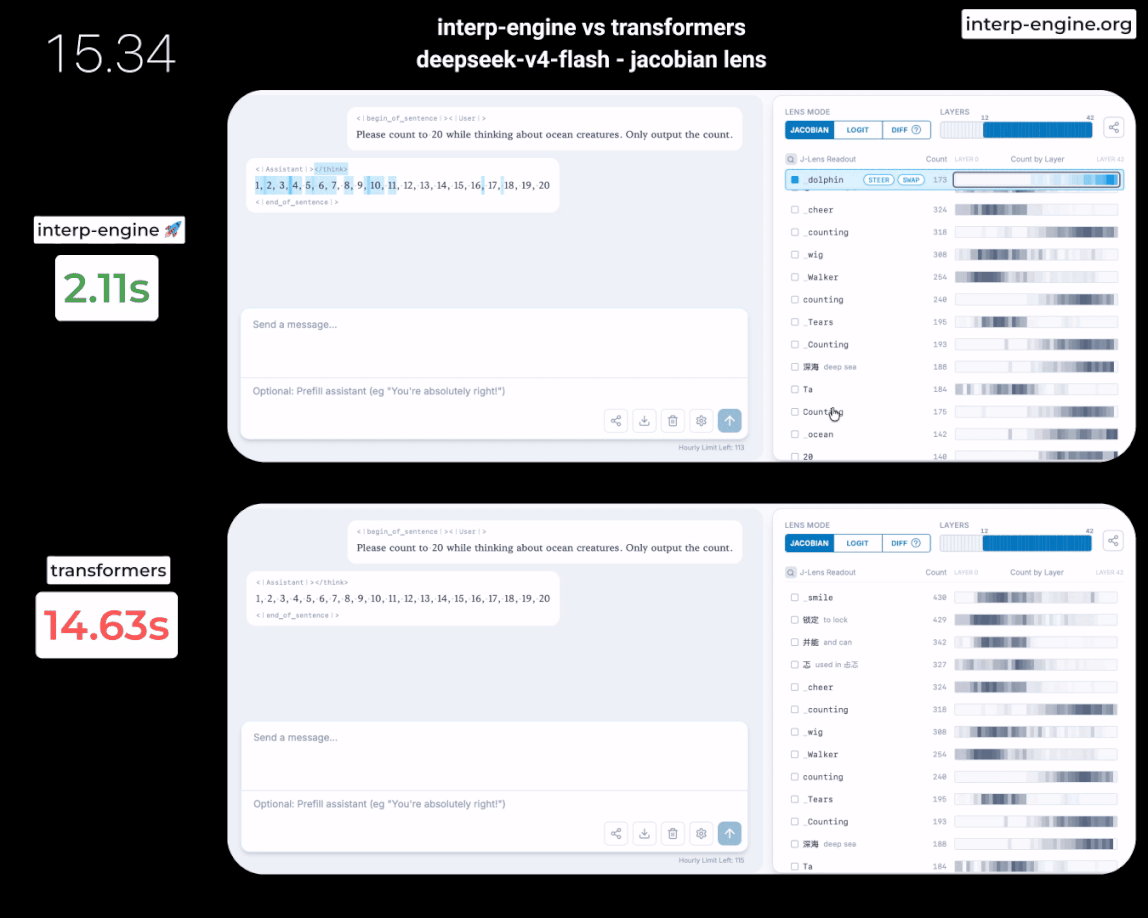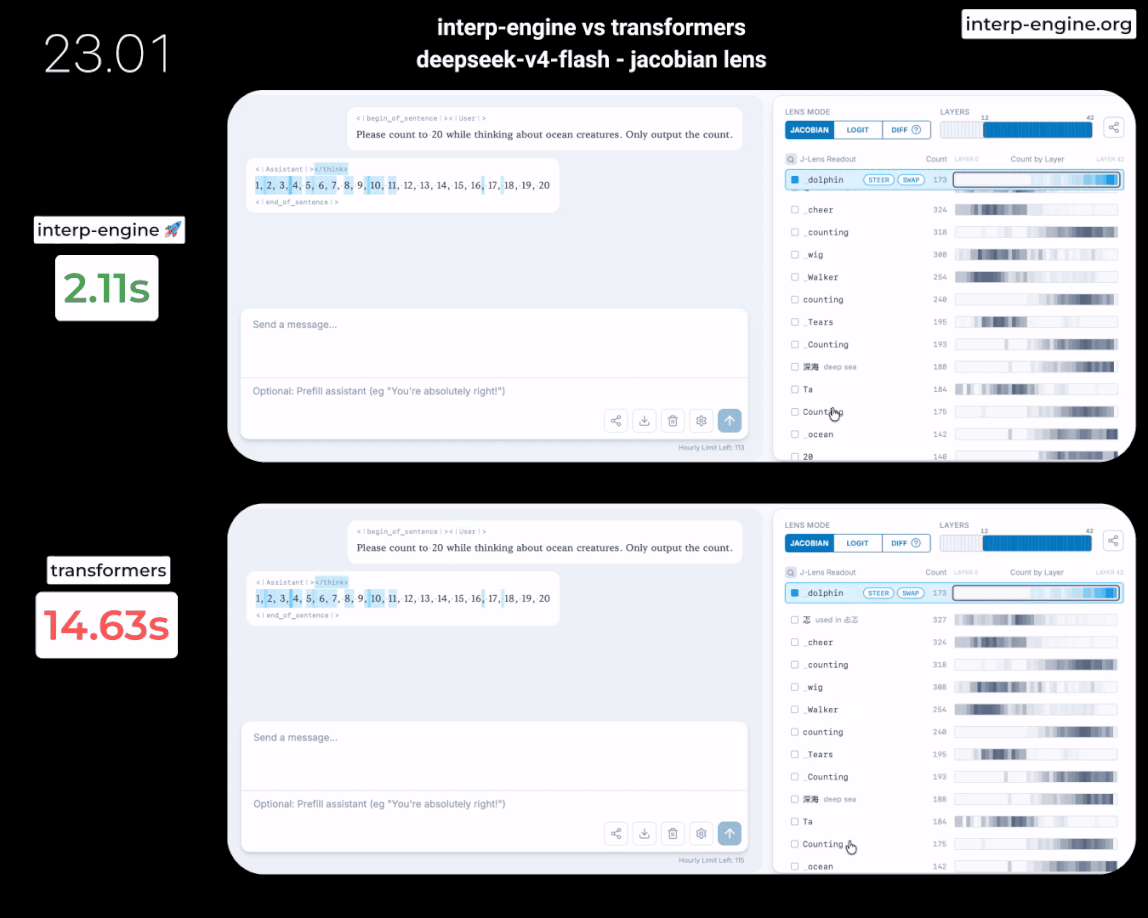
- Speed - It is built on vLLM. For large models like DeepSeek V4 Flash, it has more than 40x the throughput of HuggingFace Transformers.
- Standard hook points - 34 hook points with the same names for all architectures, from GPT-2 to Gemma 4.
- Accuracy - We compare its outputs with other interpretability libraries and with Transformers, for 50+ models.
- Easy to use - The docs start with examples. You can also ask "Riz", an AI helper on the website.
Architecture Viewer
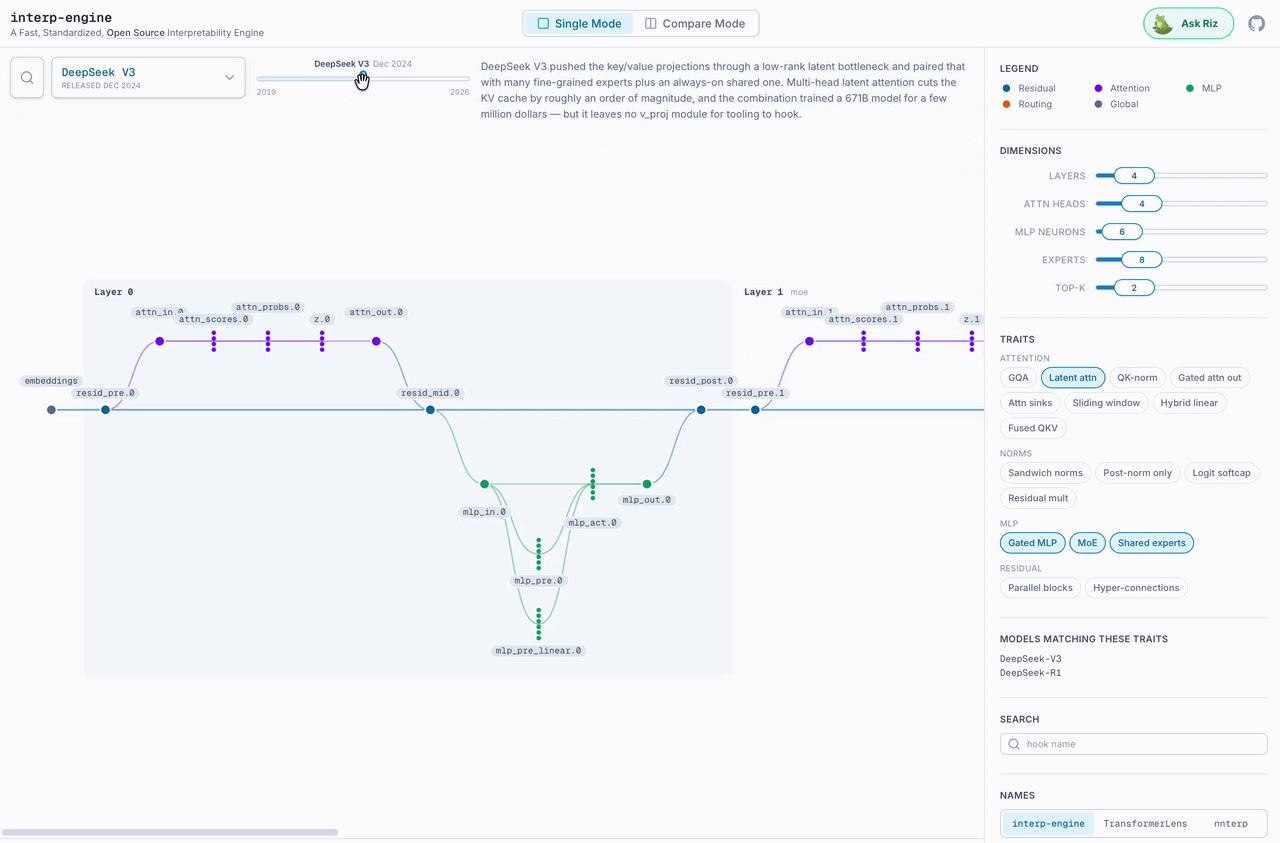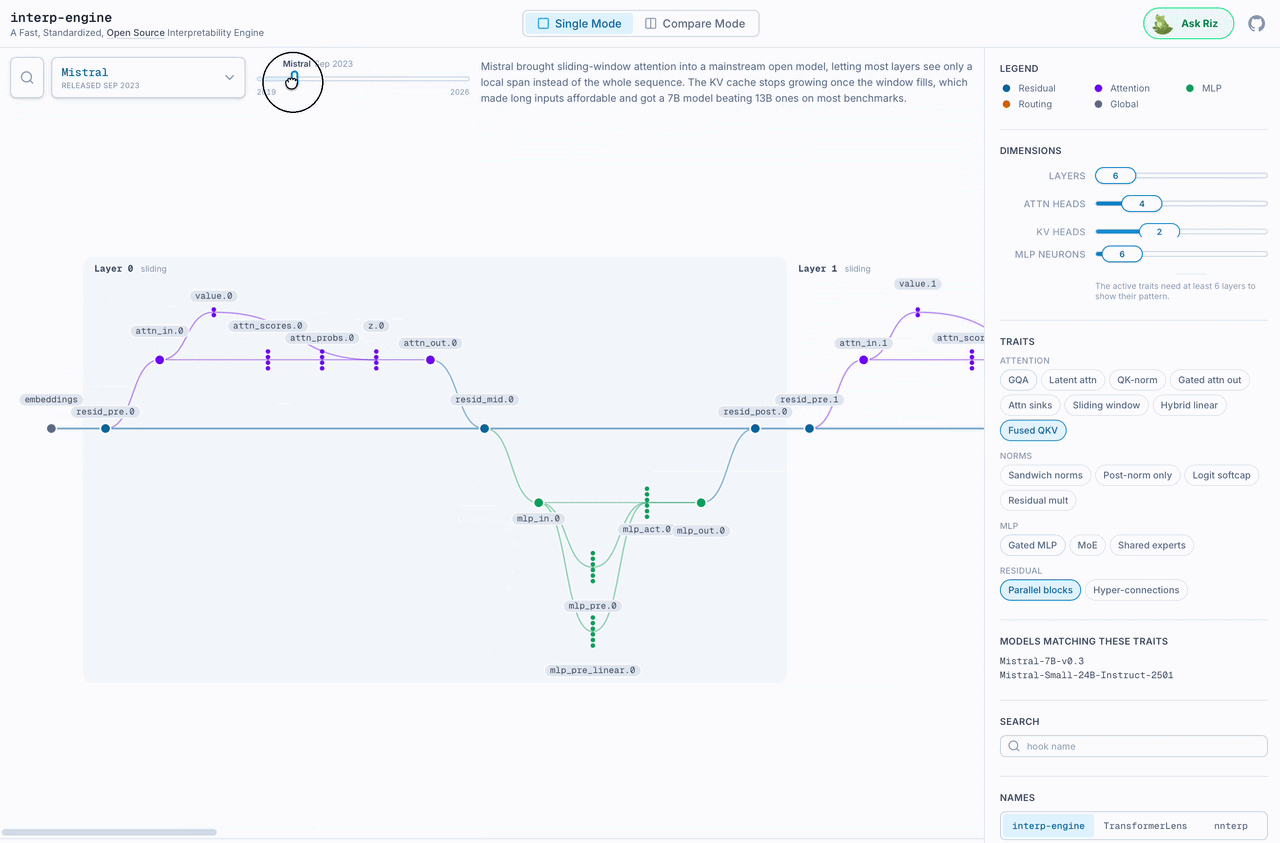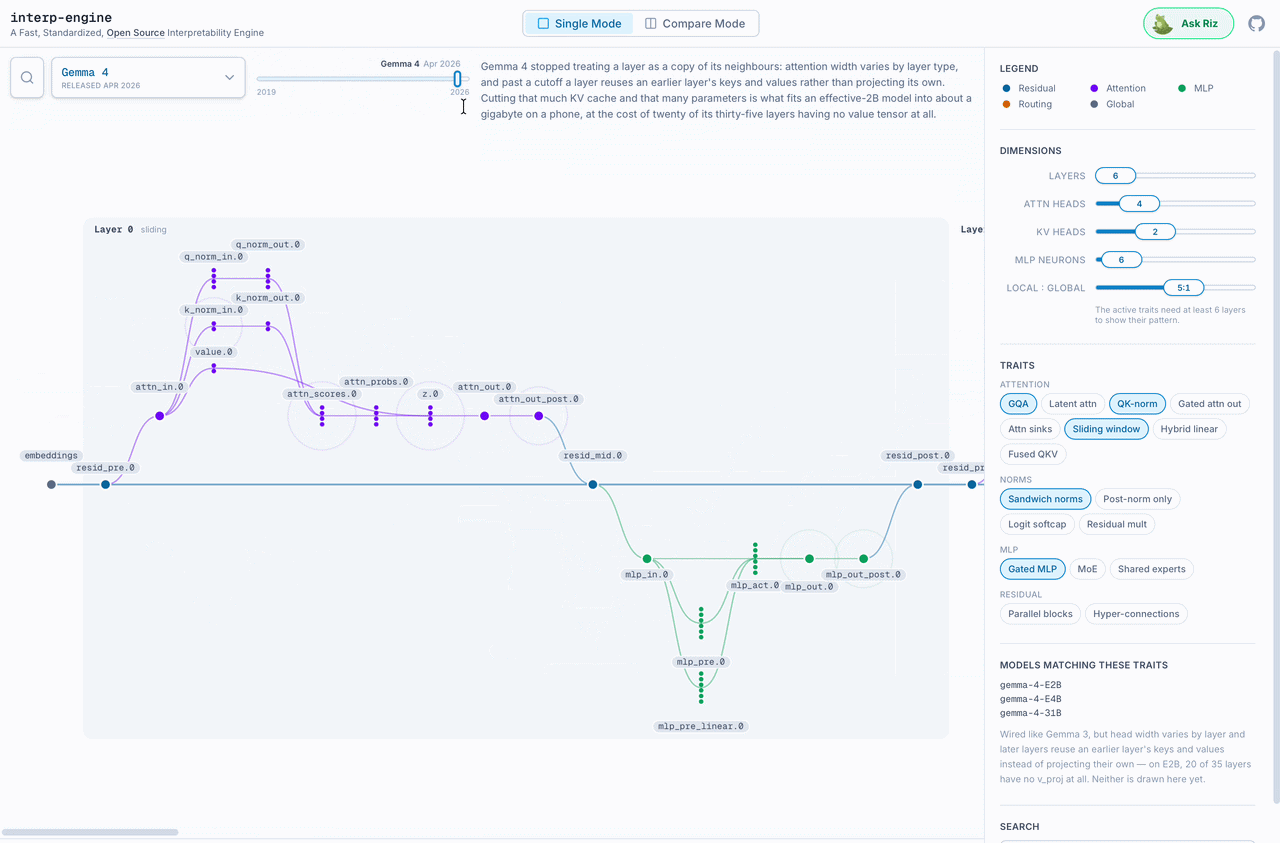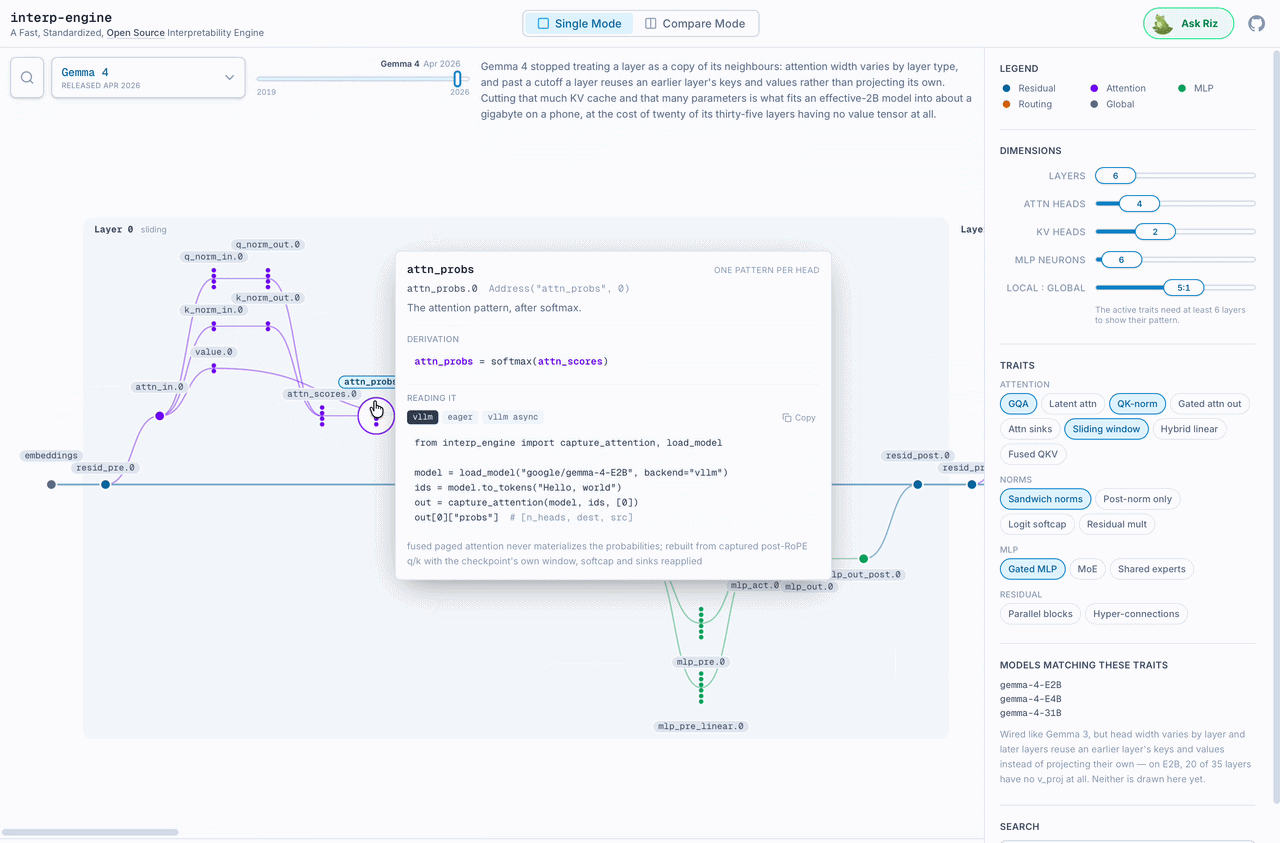
The interp-engine website shows a diagram of each model architecture. Click a hook point to see where it is, how it is calculated, and the code to read it. Click Compare to see the differences between two architectures, for example Gemma 2 and Gemma 3.
GPU Sizer
The GPU Sizer helps you find the smallest GPU setup for a model, a backend, and the hook points that you need. It shows the VRAM use, the KV cache size, and the code to load the model. It also has an API.