Introduction
What is Neuronpedia?
Neuronpedia is an open source platform for interpretability research. It lets you explore, visualize, and steer the internals of AI models. It is both:
- A public database of data from inside models: features, activations, explanations, attribution graphs, attention heads, and more.
- A set of free tools and APIs to test ideas about how models work, with no setup and no GPU.
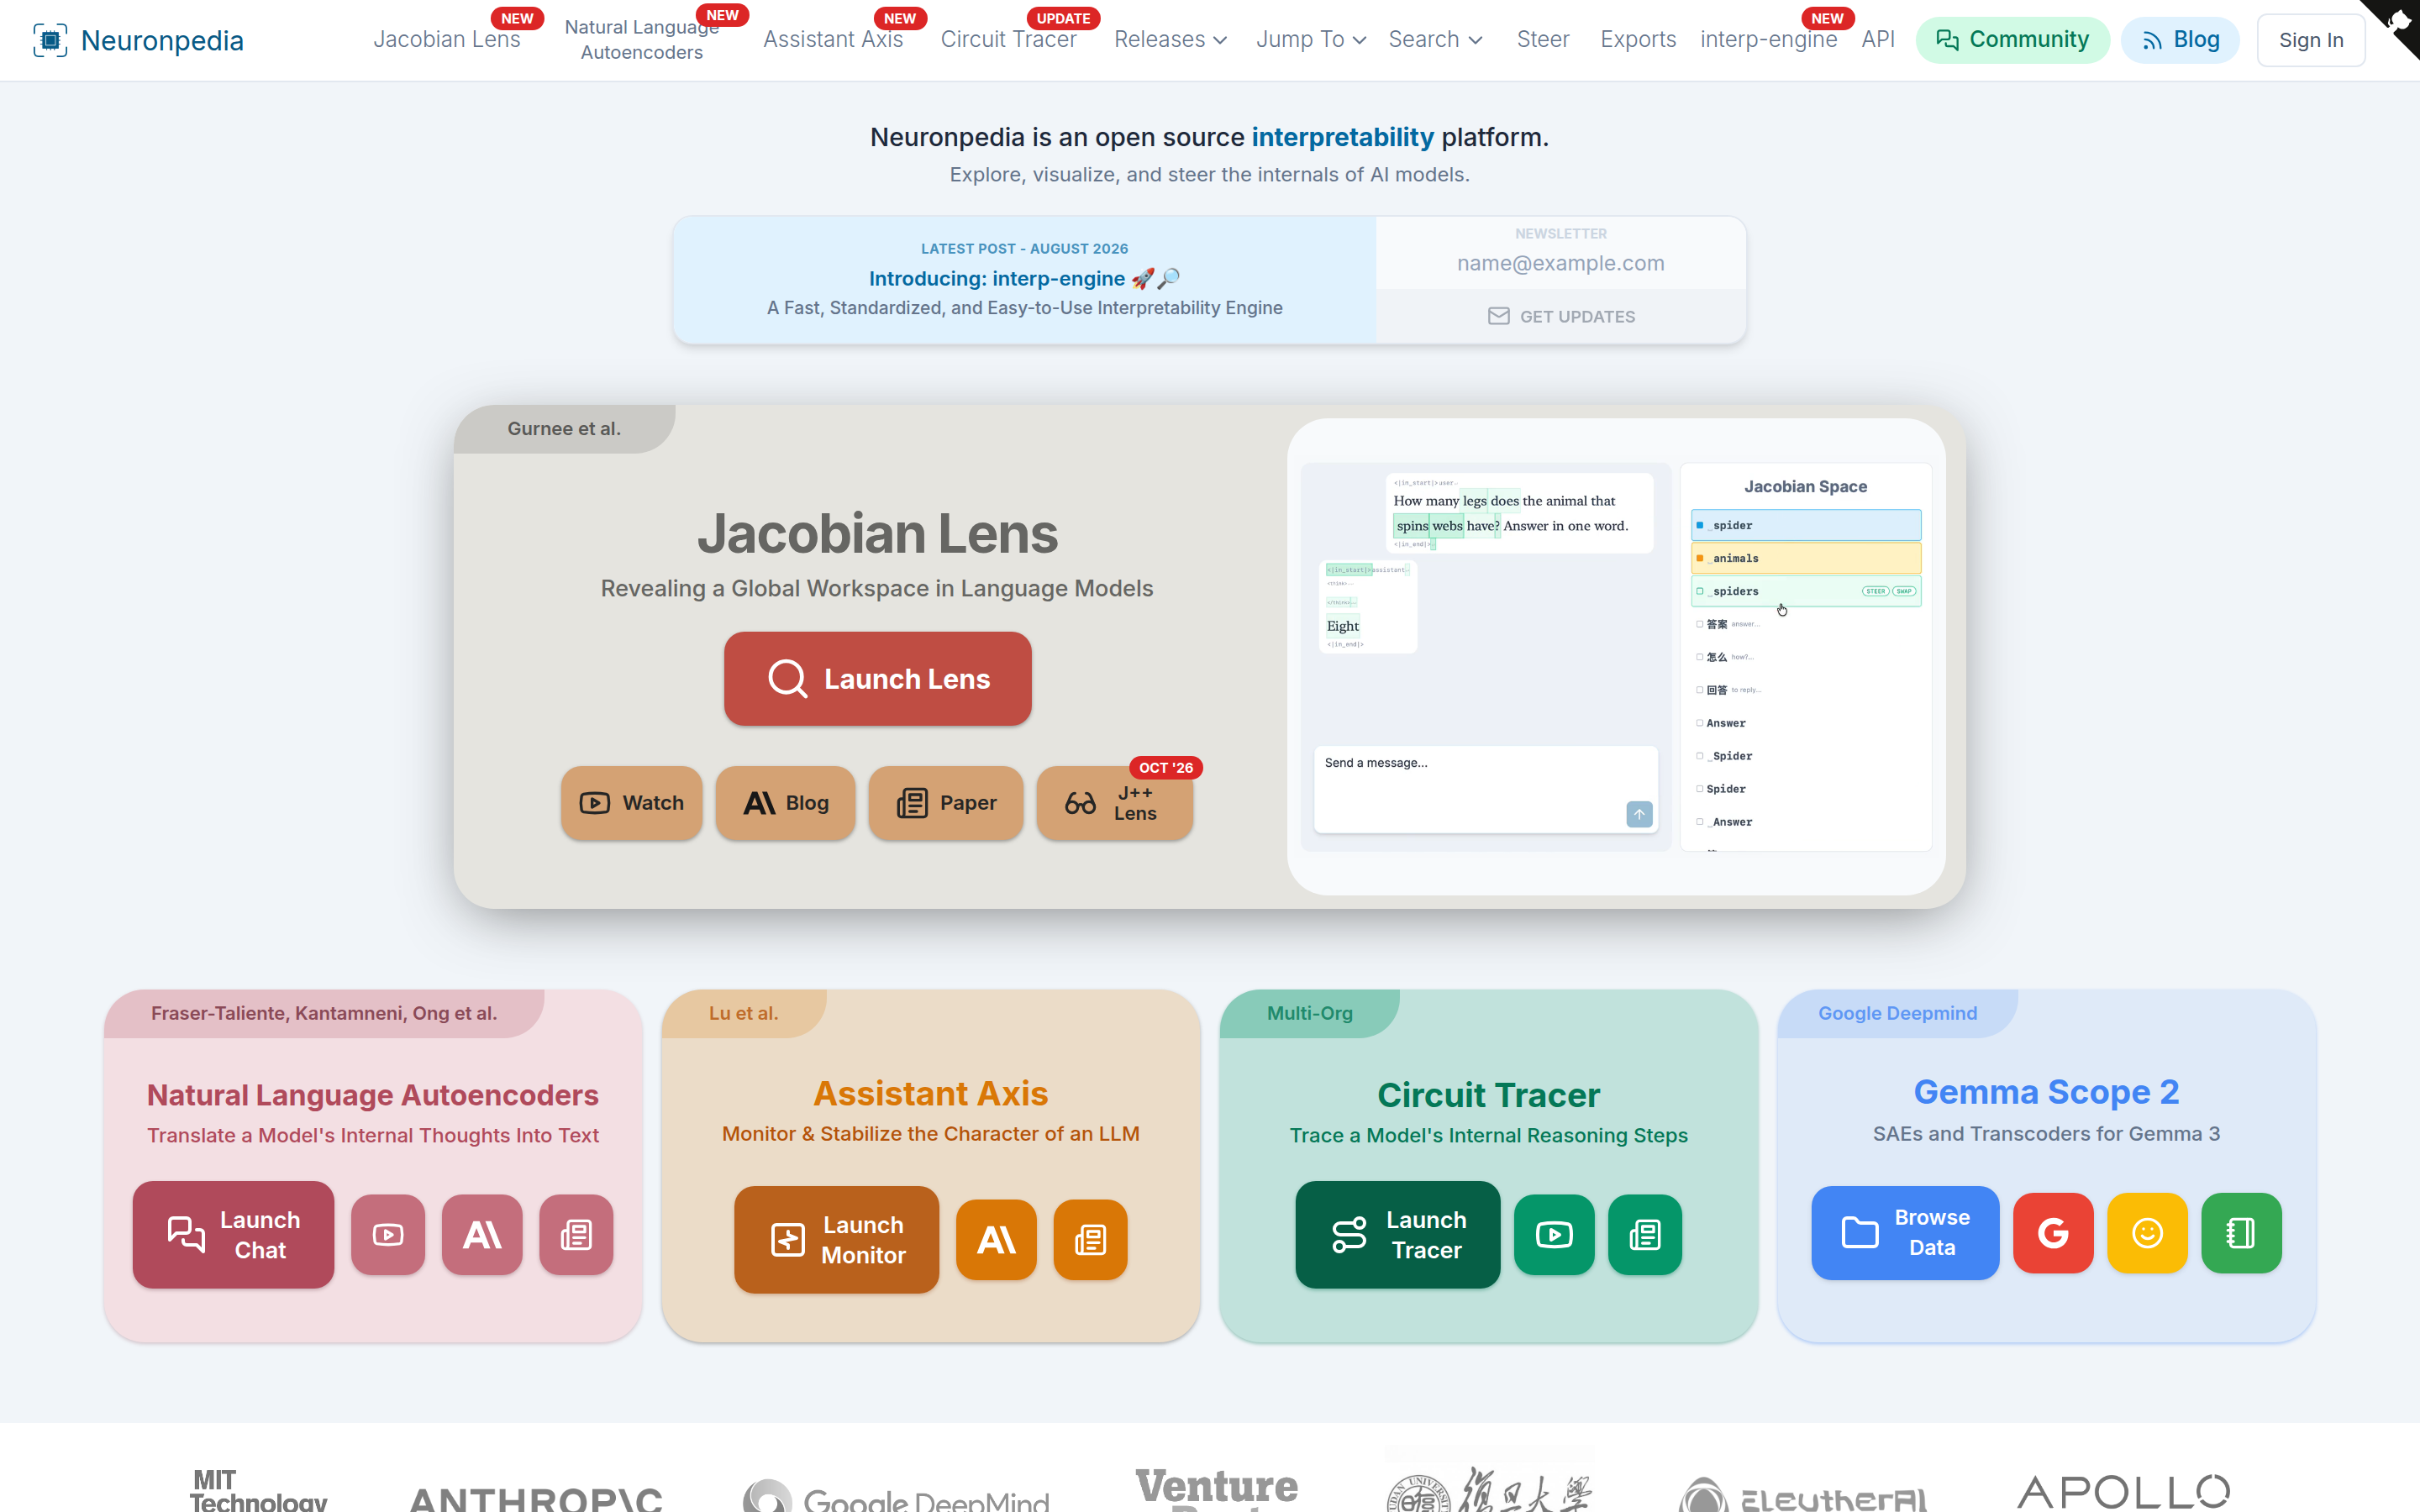
What Can I Do on Neuronpedia?
| Tool | What it does |
|---|---|
| Sparse Autoencoders | Look at features from SAEs and transcoders. Search them and test them with your own text. |
| MLP Neurons | Look at 8.6 million MLP neurons in 10 models, with explanations from community researchers. |
| Steering | Change a model's output with features or your own vectors. |
| Circuit Tracing | Make attribution graphs that show the steps inside a model as it writes. |
| Attention Heads | Explore 36,000+ attention heads in 37 models with HeadVis. |
| Jacobian Lens | See the concepts that a model "holds in mind" at each token. |
| Natural Language Autoencoders | Translate a model's activations into plain English. |
| Assistant Axis | Watch a model drift from its assistant persona, and keep it there. |
| API & Data | Use all of this from code, or download it. |
New to Neuronpedia? Start with Key Concepts.
Why Neuronpedia?
TL;DR - Researchers do research. We accelerate them by doing everything else: visualizations, tooling, sharing, scaling, and hosting.
When a research group releases new work (like SAEs, a new lens, or a new method), we put it on Neuronpedia so that anyone can use it right away. See Research Releases.
Neuronpedia is open source. The models run on interp-engine, our open source interpretability engine.
Questions?
Please email us or see Feedback & Support. We love feedback!
Launch Demo (2024)
Here's our launch tweet thread from 2024, with GIFs that show the first version of Neuronpedia:
For more background, read our launch post on LessWrong.